Vector Search Is Retrieval Design: How to Evaluate Recall, Relevance, and Latency
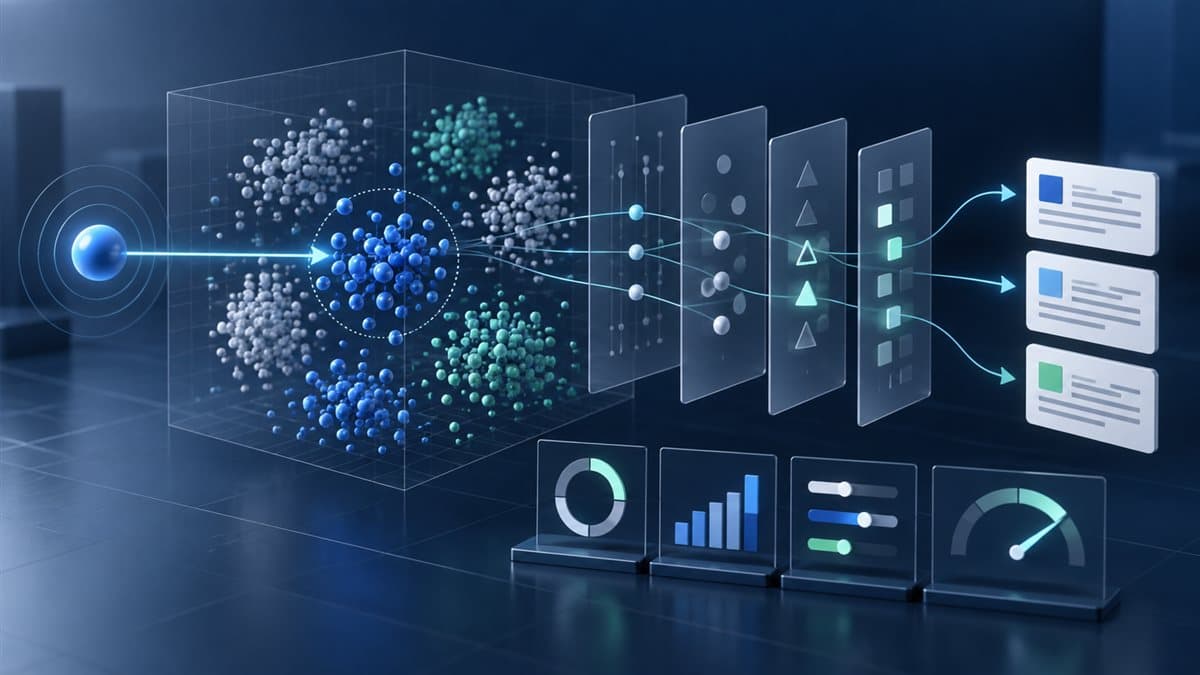
Figure: Conceptual overview of the platform.
Vector search represents documents and queries as dense vectors and retrieves candidates that are close under a chosen similarity measure. It is useful when lexical matching alone misses semantic relationships, but it is not a substitute for retrieval design. An index can return nearest vectors quickly while still returning content that is outdated, unauthorized, poorly chunked, or irrelevant to the user’s actual task.
Libraries such as Faiss make the performance trade-offs concrete: index choice, memory use, build time, recall, and query latency are coupled. The correct configuration is therefore an empirical decision made against a realistic corpus and workload, not a default copied from a tutorial.
Separate candidate retrieval from final relevance
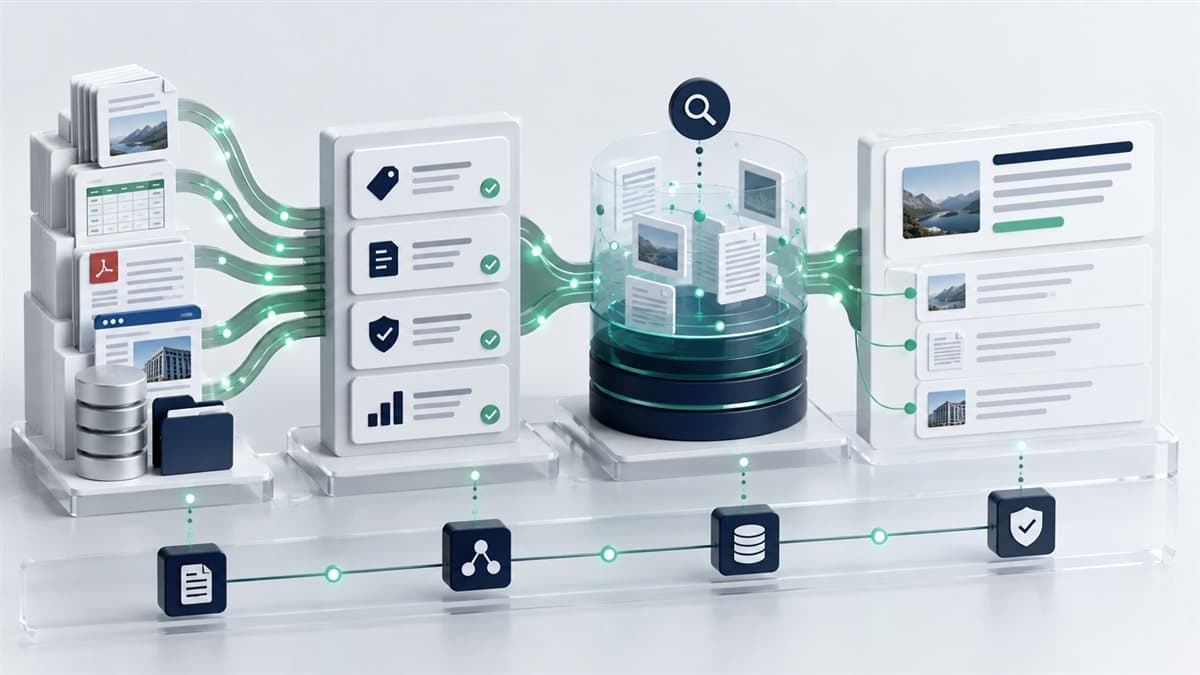
A practical retrieval path usually has more than one stage. Candidate generation retrieves a manageable set of semantically similar items. Metadata filters enforce tenant, permission, language, document type, time range, or product scope. A reranker or task-specific scoring rule can then prioritize the items that best answer the query.
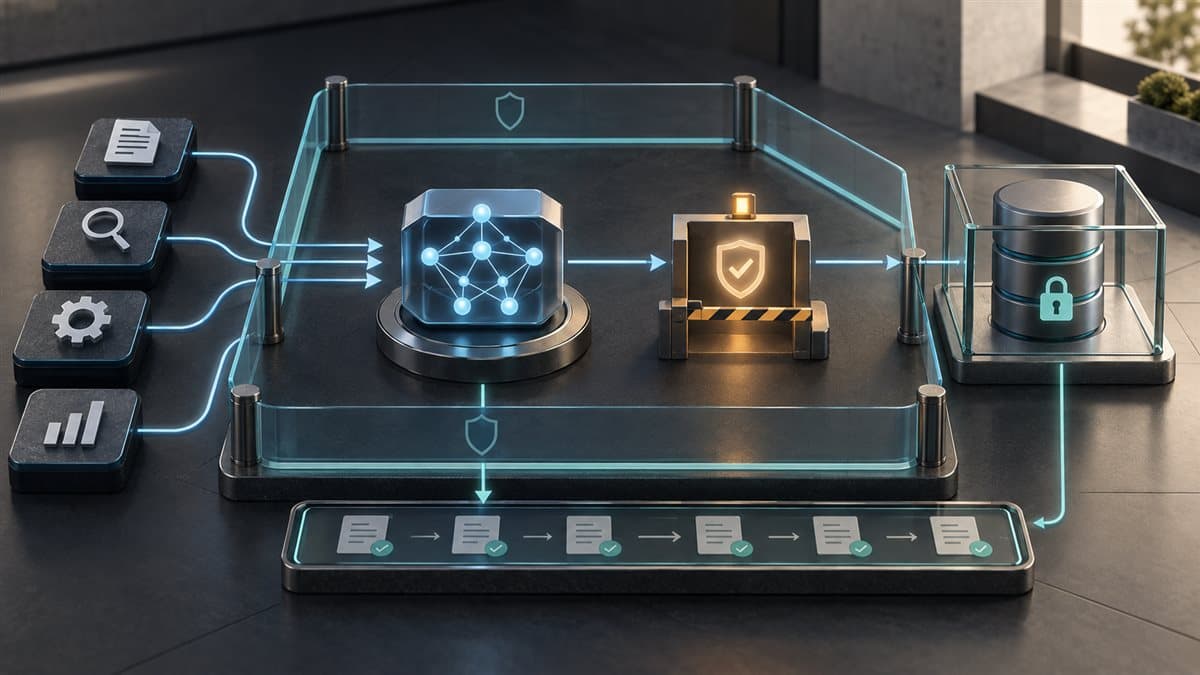
This structure matters because vector similarity does not understand business constraints by itself. Security filters must be applied as part of the retrieval path, not appended after context has been assembled. Likewise, freshness and document status belong in metadata so that a superseded policy is not treated as equal to the current one.
Benchmark the trade-off that users experience
Approximate nearest-neighbor (ANN) methods exchange some exactness for lower latency or resource use. The right question is not “which index is fastest?” but “what recall and latency are acceptable for this task at this scale?” Benchmarking should use the corpus, filters, concurrency, and query distribution the system will actually serve.
Evaluate at least three layers: ANN recall against an exact baseline, relevance against human-reviewed judgments, and end-to-end latency including embedding, filtering, reranking, and network overhead. A fast vector lookup that causes downstream reranking or model calls to dominate the request is not an end-to-end win.
- Offline: recall@k against exact search, nDCG or another reviewed relevance measure, and filter correctness.
- Operational: p50/p95 latency, throughput, index-build duration, memory footprint, and failure rate.
- Product: answer support rate, successful task completion, zero-result rate, and user correction signals.
Use hybrid retrieval when the task needs it
Semantic vector search is powerful when intent is expressed in different words from the source material. It is less reliable for exact identifiers, product codes, legal phrases, and short queries where lexical precision matters. Hybrid retrieval combines lexical and vector candidates, then applies filters and ranking rules appropriate to the domain.
The choice should follow observed failure cases, not a blanket preference for one retrieval method. Review the queries that produce poor results, classify whether the failure is lexical, semantic, metadata-related, or caused by stale content, and improve the retrieval design at that layer. This gives search quality a repeatable engineering feedback loop.
A data-platform view of vector retrieval
Vector indexes deserve the same production discipline as analytical tables. Version embeddings and models, record source and chunk lineage, monitor index freshness, validate access boundaries, and make rollback possible. When an embedding model changes, the impact is not limited to a model setting: it can alter retrieval results across the whole corpus.
This is the connection between data platform engineering and AI-ready systems. The useful outcome is not merely an index of vectors; it is a governed retrieval capability with observable quality, clear ownership, and reliable operations.
In retrieval-augmented generation, these controls form the evidence layer that makes answers reviewable; see RAG Is a Data Product, Not a Prompt for the broader system design.